All Topics
Transformers & Attention
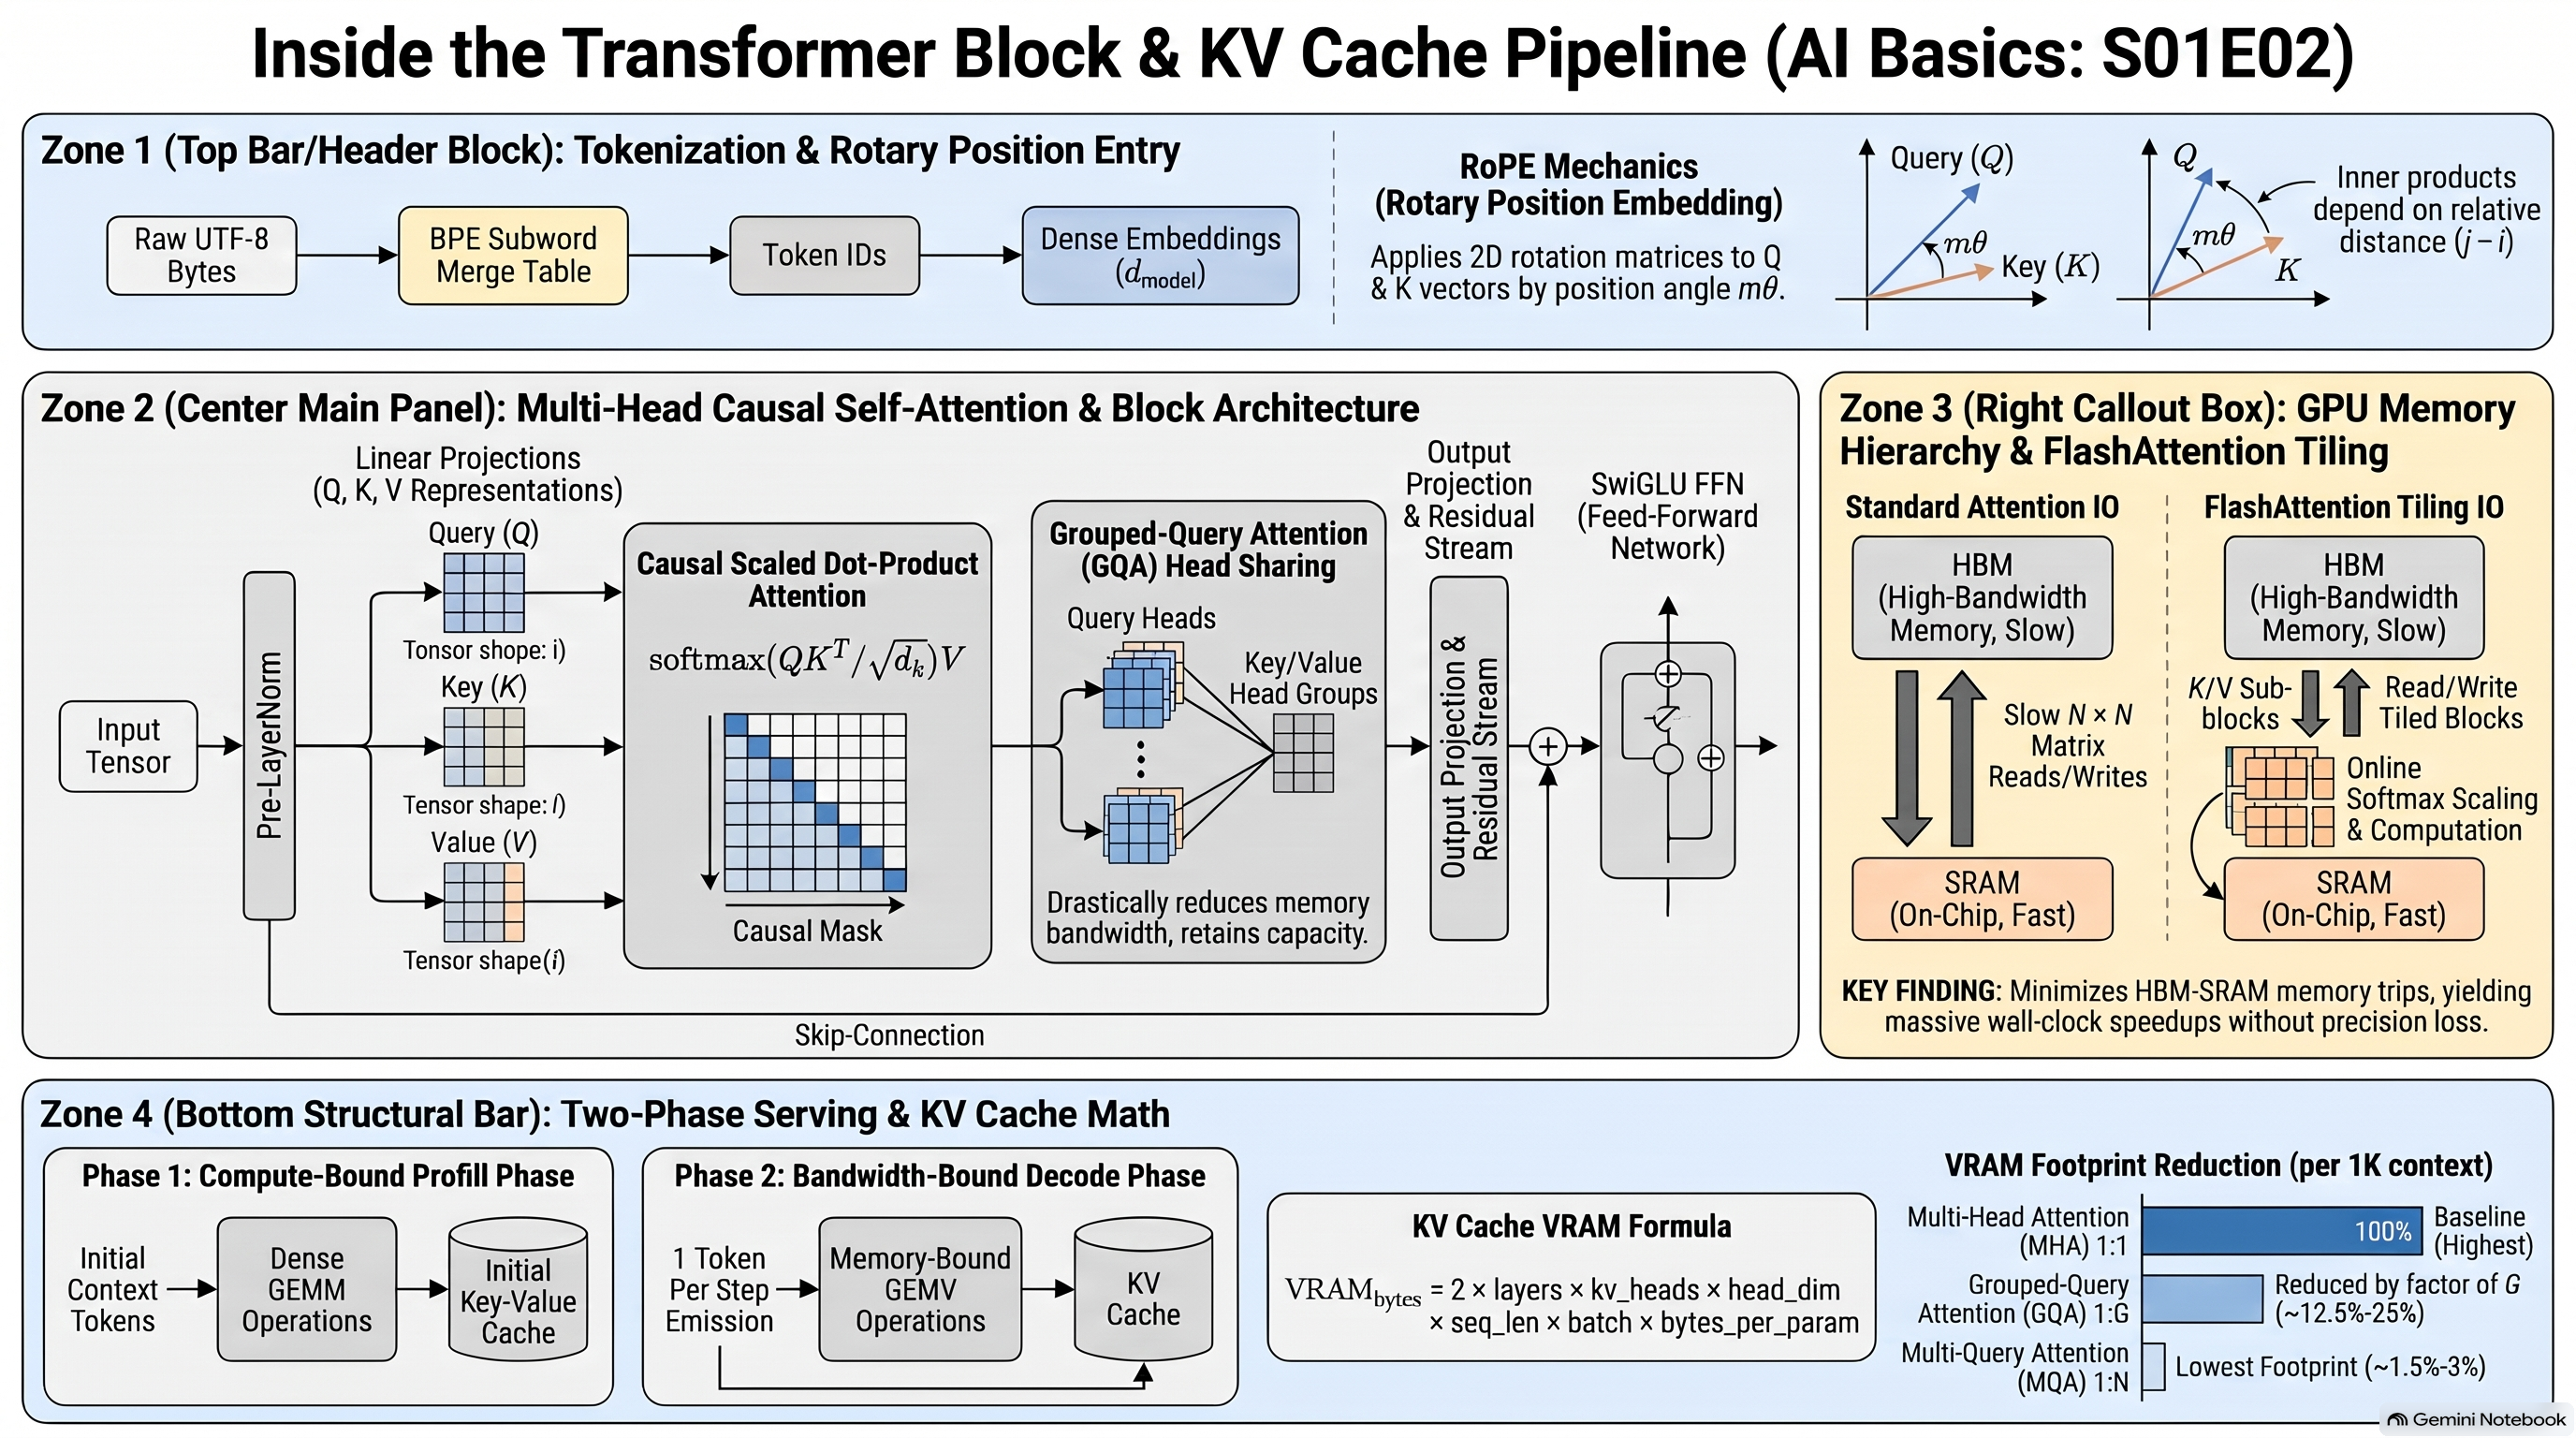
How attention lets a transformer relate every token to every other, why that cost grows quadratically, and the tricks, like the KV cache, that keep it fast.
AI FoundationsAI
Videos (2)
Podcasts (1)
Slide decks (1)
Infographics (1)
Sources (13)
- web page Attention? Attention! | Lil'Log
- web page Cache strategies · Hugging Face
- web page The Illustrated BERT, ELMo, and co. (How NLP Cracked Transfer Learning) – Jay Alammar – Visualizing machine learning one concept at a time.
- web page The Illustrated GPT-2 (Visualizing Transformer Language Models) – Jay Alammar – Visualizing machine learning one concept at a time.
- web page The Illustrated Transformer – Jay Alammar – Visualizing machine learning one concept at a time.
- web page The Transformer Family Version 2.0 | Lil'Log
- web page Tokenization algorithms · Hugging Face
- web page [1508.07909] Neural Machine Translation of Rare Words with Subword Units
- web page [1706.03762] Attention Is All You Need
- web page [1810.04805] BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
- web page [2104.09864] RoFormer: Enhanced Transformer with Rotary Position Embedding
- web page [2205.14135] FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- web page [2305.13245] GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints