OLTP vs OLAP
Transcript
Made automatically from the video's sound, so it may contain mistakes. Click a line to play from there.
Welcome back to the Explainer. Hello, today we're skipping all the basic introductory theory. Instead, we're diving straight into a byte-level architectural teardown of row-oriented versus column-oriented storage engines.
No fluff whatsoever, just the raw mechanical realities of modern data stores and the hard engineering choices you actually have to make. Let's jump right in by recalling our workload landscape map from the previous explainer.
This is the absolute golden rule. Your application's read and write patterns must ruthlessly dictate your storage architecture. Literally every single database workload sits somewhere on a spectrum.
On one end you've got your single row point mutations, and all the way on the other, massive analytical aggregations. So here's our highly technical agenda for today. We're doing a comparative deep dive across five critical mechanical layers.
The OLTP slotted heap, Postgres' indexing toolkit, Columna engines and vectorization, write paths and LSM trees, and finally quantified OLAP decision boundaries. Right, let's kick things off with section one, the OLTP slotted heap, looking specifically at byte-level row store architecture.
To really grasp this, we need to look at the traditional disk-level structures of engines like PostgresQL and SQL Lite. What you're looking at here is a standard 8 kilobyte slotted heap page layout. Notice how a whole row's data is packed entirely contiguously.
You've got your 24-byte page header data block, and then those item ID data line pointers, basically offset and length pairs aiming straight at the data. Down at the bottom, there's the heap tuple header data, which holds the TXmin and TXmax transaction IDs for multiversion concurrency control.
It's a brilliant bit of engineering, and it perfectly illustrates why row stores are absolutely incredible for single row lookups. All your data and all the concurrency control is just sitting right there in one continuous memory block.
But of course, there's always a catch, isn't there? The explicit trade-off for using write-ahead logging to get those lightning fast sequential crash recoveries is that your MVCC updates generate dead tuples. Think about it.
When you update a row, Postgres doesn't just overwrite it in place. It writes a brand new version and leaves the old one behind. This means the autovacuum daemon has to constantly run background space reclamation. It's a really delicate mechanical balance, and let's be honest, it's a balance that has probably ruined at least one of your weekends.
PostgresQL's indexing toolkit, unpacking read paths and heap fetch mechanics. Now, Postgres mitigates the heavy cost of scanning those raw heap pages by giving you a diverse, highly specialized indexing toolkit. It's like a Swiss Army knife.
You've got standard B trees for your typical O log N leaf chain lookups. Then there are GIN indexes, which are absolute beasts for complex JSON B payloads and full text search. You've got GIST for geospatial ranges, and Bryn, block range indexes that keep really lightweight min max summaries for massive append-only time series data.
It literally gives you surgical precision over how you retrieve your data. Which brings us to a massive question about read paths. If you run an index-on scan that covers every single requested column using an include clause, why on earth would the execution engine ever fall back to reading the physical heap?
I mean, if the index already has all the answers, why bother going to the disk at all? Well, it all comes back to concurrency control. If the visibility map hasn't been recently updated by the auto vacuum process, the engine has no choice.
It's forced to perform a random heap fetch just to check the tuples header to confirm it's actually visible to your current transaction. Honestly, dirty visibility map bits are the silent killers of index-only scan performance.
This is the exact reason why a perfectly indexed query might just suddenly start tanking your disk IO out of nowhere. Right, let's pivot to section three, columnar engines and vectorization, where we unpack the OLAP paradigm.
Now we're looking at the analytical side of things, digging into the mechanics of OLAP engines like ClickHouse, DuckDB, and the Apache Arrow format. To get around the massive overhead of interpreting data row by row, these databases use SIMD vectorized execution.
This was a huge architectural leap, heavily inspired by academic systems like MonADB and X100. Basically, they maximize CPU cache efficiency by shoving thousands of values through execution pipelines in a single CPU instruction, rather than agonizingly passing everything row by row.
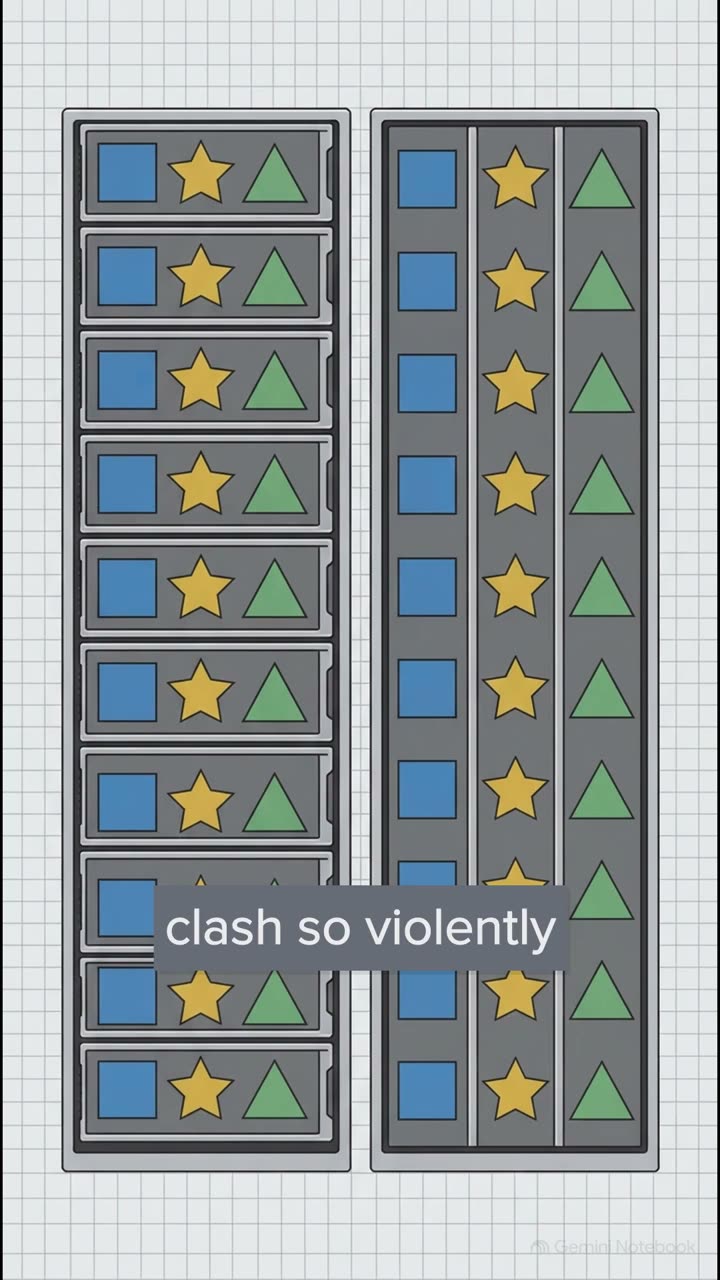
Take a look at how Clickhouse's merge tree and the parquet format pull this off physically. By storing data in these tightly compressed homogenous columns and chunking them into specific blocks, typically granules of 8,192 rows, engines can use some really aggressive dictionary and run-length encoding compression.
And because the data is just so neatly organized, engines like ClickHouse can keep sparse primary indexes entirely in RAM. This means they can rapidly skip over massive blocks of totally irrelevant data when running analytical scans.
It's incredibly efficient. Let's shift gears to section 4, write paths and LSM trees, looking at the actual cost of mutating this columna data. So how do these columnar systems actually handle writes if they don't have those slotted heat pages we saw in Postgres?
Well, they fundamentally rely on log structured merge trees. What happens is data gets buffered first into a memory-based C naught tree. Then, once it hits a certain temperature threshold, a rolling merge process sequentially compacts that data into a disk-based C1 tree.
So it's this continuous ongoing process of writing brand new immutable files rather than updating existing blocks in place. Now here is the absolutely crucial trade-off. While B trees in row stores can execute point mutations in place perfectly, those exact same single row update and delete commands will completely wreck column LSM engines.
They turn into severe compaction bottlenecks because of massive write amplification. The takeaway? You simply cannot treat an OLAP engine like an operational database. If you try, you'll grind it to an absolute halt for sure.
Finally, we arrive at section 5, quantified OLAP decision boundaries. Let's define exactly when you should actually migrate off your primary database. When we weigh these architectures side by side, the trade-offs are incredibly stark. Just look at the comparison.
On one hand, you've got engines like Postgres and SQLite giving you sub-millisecond point lookup latency. On the other, DuckDB and ClickHouse offer absolutely massive hundred million row aggregation throughput and extreme compression ratios.
But pay close attention to the differences in acid isolation levels, like red committed versus serializable. And, as we just discussed, notice how simple update and delete operations heavily penalize the columnar systems with write amplification.
Okay, so what does this all mean for you? Let's bring it all together. The hard engineering rule of thumb is that it strictly depends on your throughput. Honestly, you should comfortably stay right where you are on an indexed Postgres QL database, maybe using partition JSON B, if your application is pushing fewer than 5,000 write transactions per second.
Prematurely adding a secondary analytical system before you hit that threshold, it's just going to give you massive architectural headaches. On top of that, a dedicated OLAP engine is generally total overkill if your actively queried hot working set fits cleanly within 50 to 100 gigabytes of RAM.
Modern servers are beasts. They can easily cache this entire footprint in memory, which allows Postgres to aggregate the data incredibly quickly for the vast majority of operational use cases. But look, inevitably, your data is going to scale into the terabytes and petabytes.
And when those massive analytical scans start to completely choke your primary database's CPU and ruthlessly evict your hot cache, which is a painful scenario I'm sure a lot of you recognize, you have to ask yourself, what architecture comes next?
When embedded engines like DuckDB just aren't cutting it anymore, where on earth do you go? Well, we are going to answer that exact question in episode two of this explainer. We'll be tearing down the mechanical differences between data warehouses, data lakes, and lake houses.
Until then, respect your workloads and measure your bottlenecks. Take a hard look at your own primary database today. Are you already operating way past these mechanical boundaries without even realizing it?
Have a think about it, and I'll see you in the next one.