All Topics
Quantization & LoRA
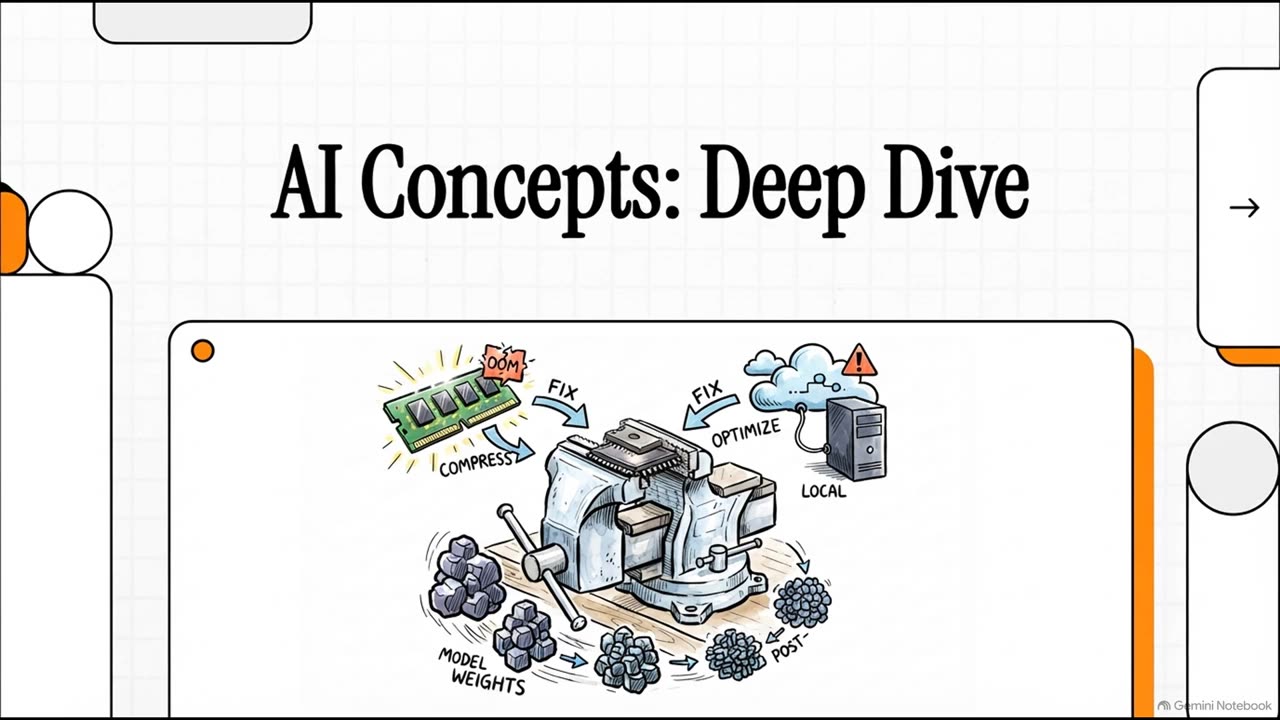
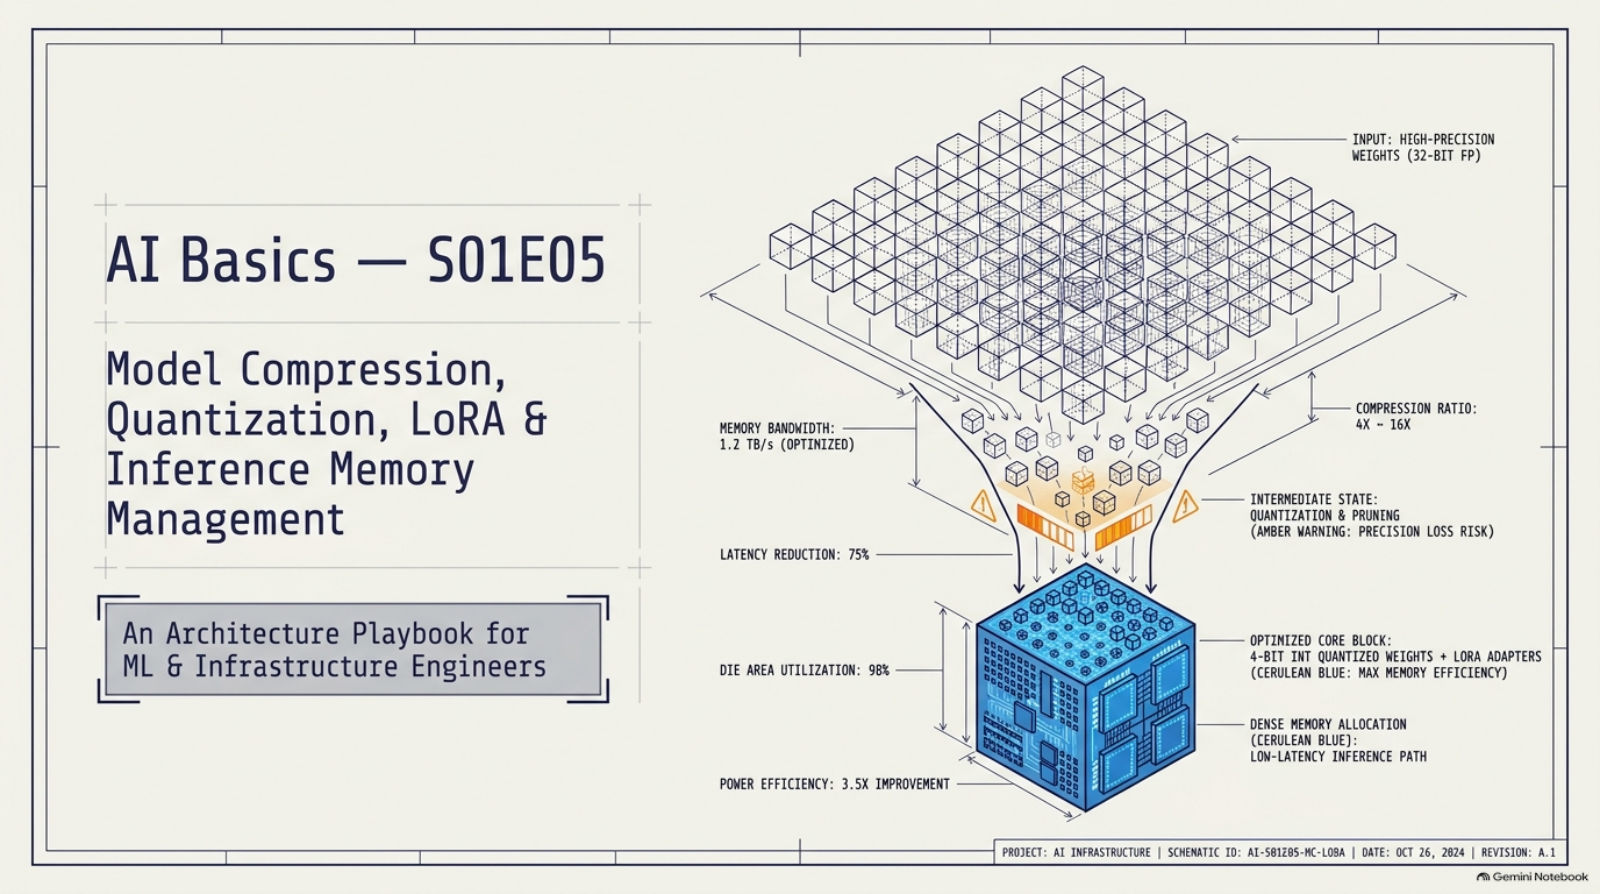
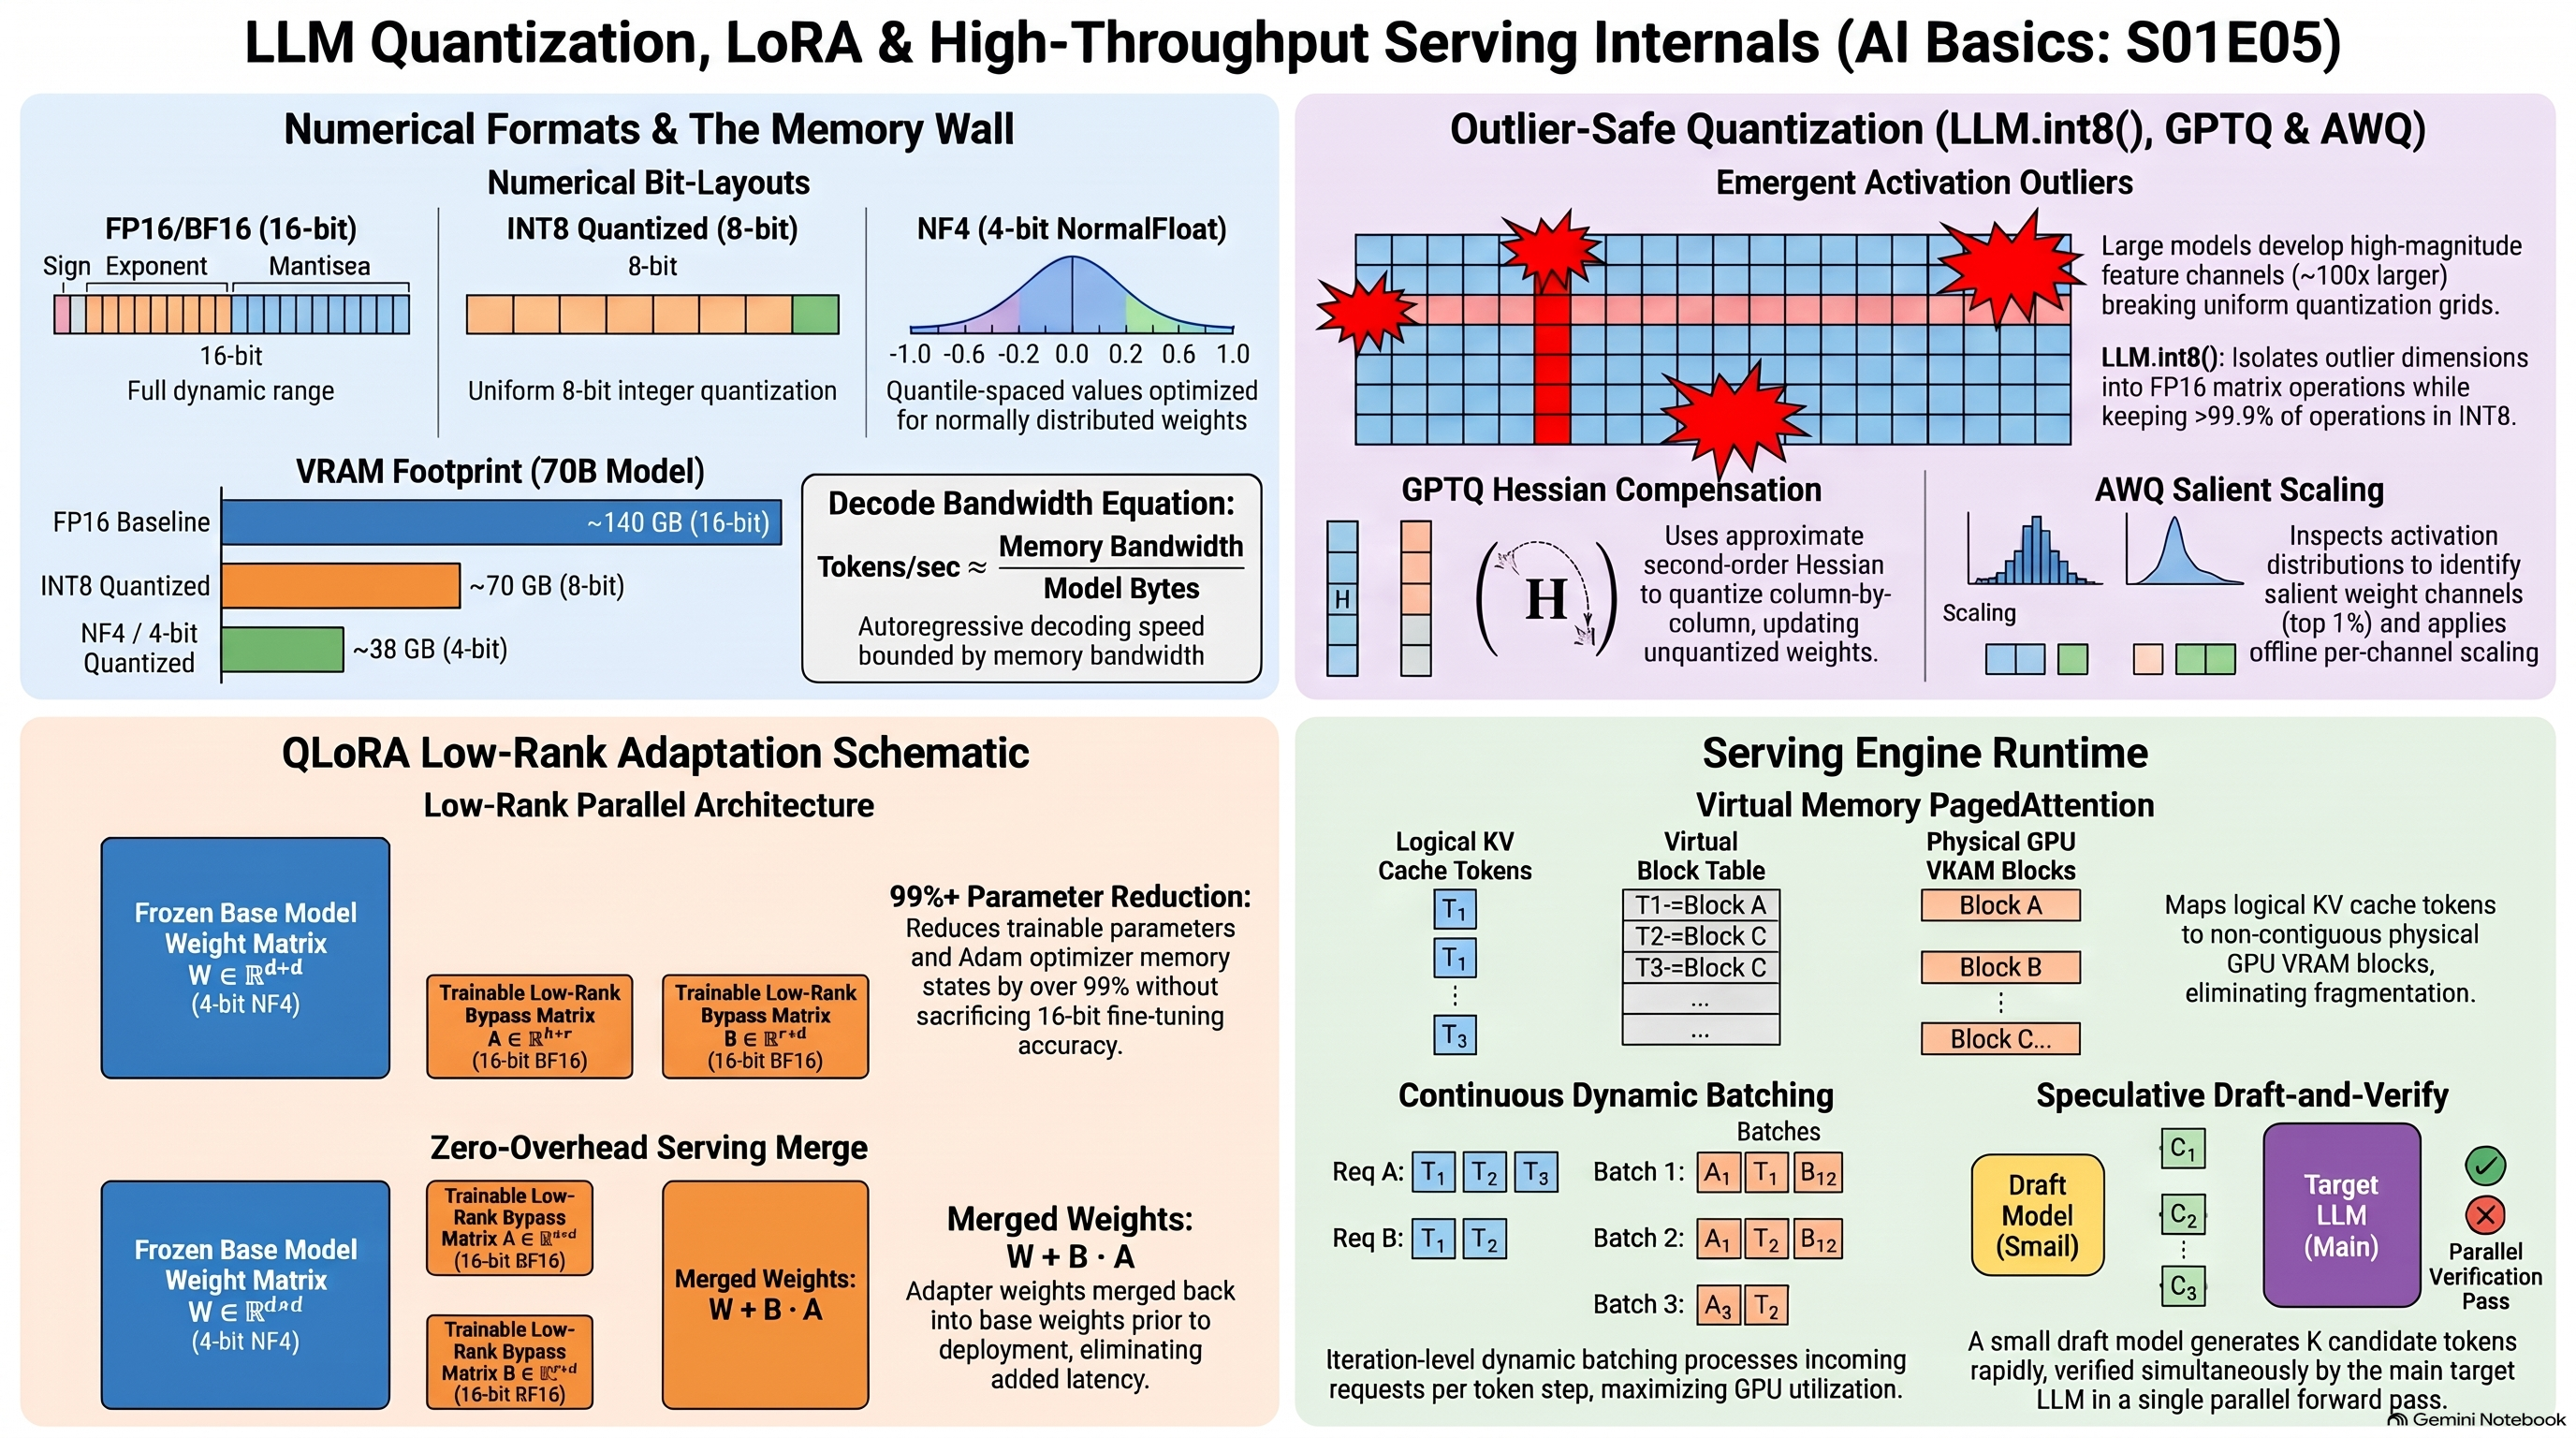
Why large language models hit a memory wall, and how quantisation and LoRA shrink models and fine-tuning so they fit and run fast on real GPUs.
AI FoundationsAI
Videos (2)
Podcasts (1)
Slide decks (1)
Infographics (1)
Sources (12)
- web page Bitsandbytes · Hugging Face
- web page Large Transformer Model Inference Optimization | Lil'Log
- web page PEFT · Hugging Face
- web page Quantization · Hugging Face
- web page [1503.02531] Distilling the Knowledge in a Neural Network
- web page [2106.09685] LoRA: Low-Rank Adaptation of Large Language Models
- web page [2208.07339] LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
- web page [2210.17323] GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
- web page [2305.14314] QLoRA: Efficient Finetuning of Quantized LLMs
- web page [2306.00978] AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration
- web page [2309.06180] Efficient Memory Management for Large Language Model Serving with PagedAttention
- web page bitsandbytes · Hugging Face